Iceberg Manifest File Structure and Its Effect on Query Planning Speed
Organizing metadata layers and file grouping determines how fast Iceberg can plan queries.
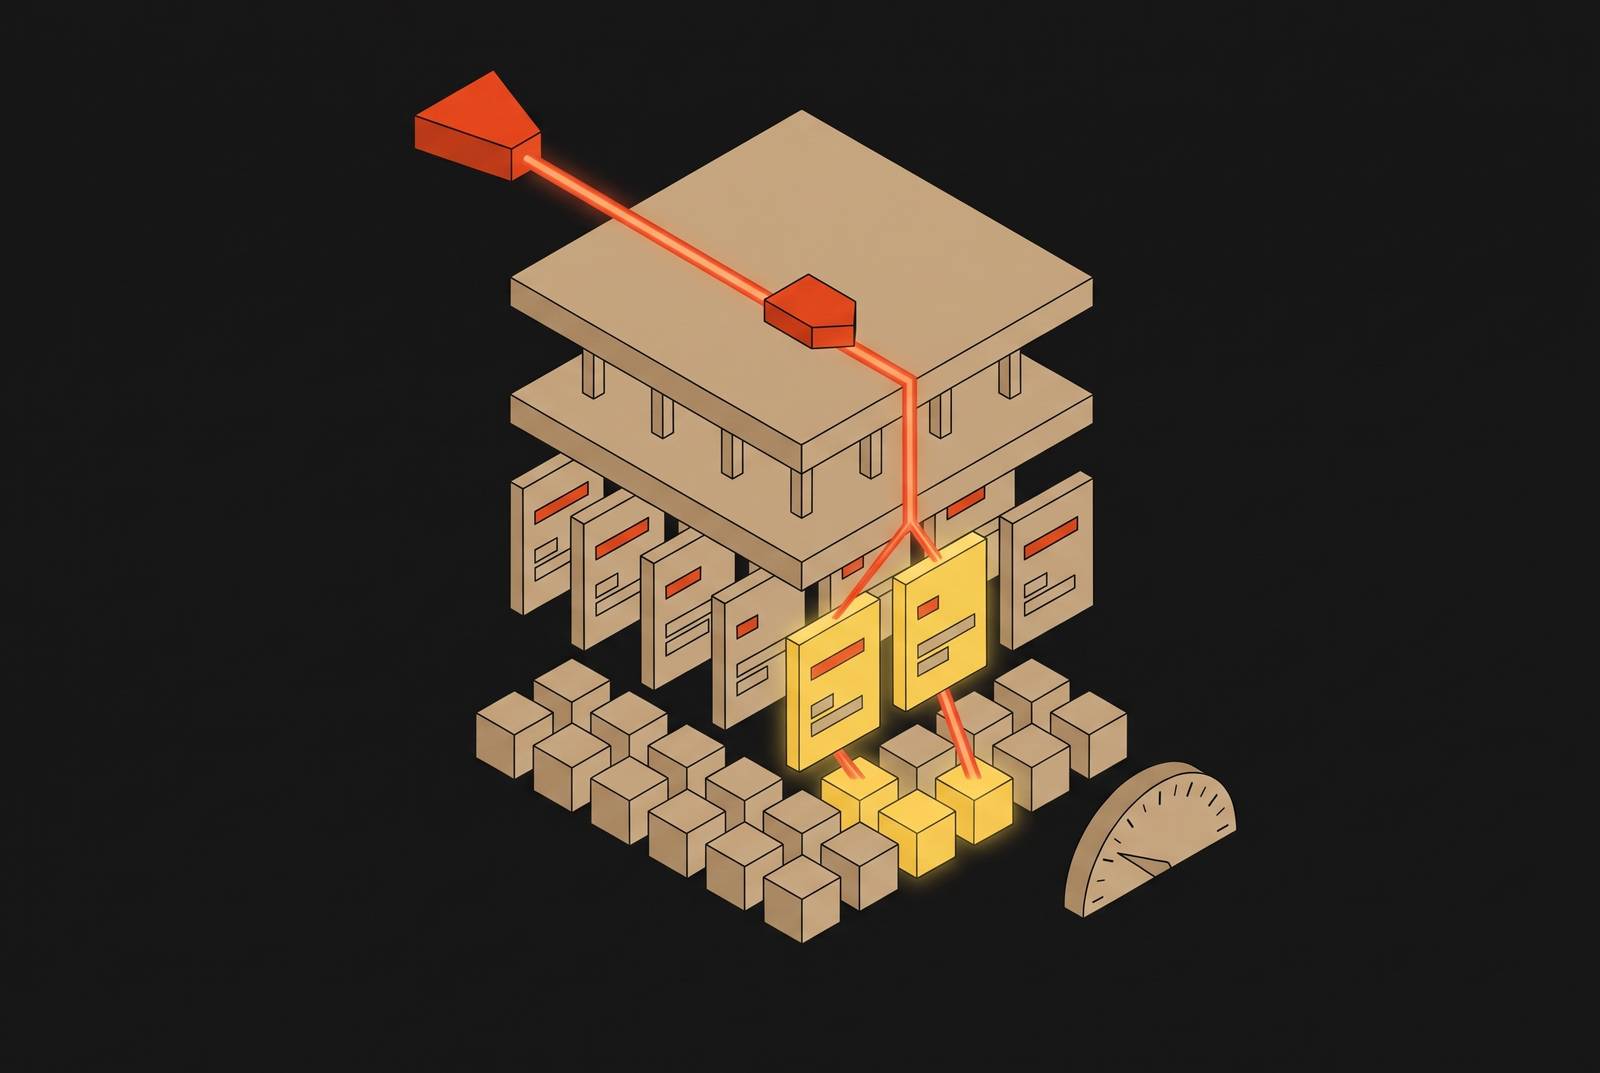
Iceberg’s manifest file structure determines how much work a query planner can avoid before reading data. Its strength is a layered metadata tree that rules out files early. Its weakness appears when that tree becomes fragmented or costly to decode. Fast planning depends on how metadata is organized as well as on storage speed or compute capacity.
Why query planning in Iceberg is a metadata problem, not a data problem
Hive-style tables mapped partitions to folders, so finding files meant listing objects across nested prefixes. Those listings became slow and costly, and were subject to throttling when the load was high. Iceberg tracks individual files. The planner reads an exact inventory for a particular snapshot, enriched with statistics that help it decide which files a query needs.
That changes where the early work happens. Before an executor reads data, the planner must traverse metadata and eliminate files that cannot match. A slow query can therefore spend its time processing descriptions of data before the data scan begins. More compute for the eventual scan does not address that delay. Diagnosing that delay starts with what the planner had to read to assemble the scan.
The three-tier metadata hierarchy and what each layer does for the planner
The hierarchy begins above the manifests themselves. A small JSON metadata file holds schema versions, partition specs, sort orders, snapshot history, and the current snapshot pointer. That snapshot represents the table at a point in time. In v1–v3, it points to a manifest list, which points to manifest files, which describe data files. The proposed v4 structure replaces the manifest list with a root manifest.
The manifest list provides the first useful summary. It is one Avro file per snapshot, with one row per manifest. Each row has the manifest’s path and length, partition spec, adding snapshot, and counts of files and rows by status. Crucially, its partition summaries contain lower and upper bounds and indicators for nulls and NaNs across the files that manifest tracks. These summaries let the planner decide whether to skip a group without opening the list of files in it.
Each entry inside a manifest describes a single data or delete file. An entry has a path, partition tuple, record count, and per-column statistics in maps keyed by column ID. Those maps have column sizes, value counts, null and NaN counts, and lower and upper bounds. The three planning tiers are therefore the manifest list, manifests, and per-file statistics, with the statistics embedded in manifest entries. Manifests are immutable and reusable across snapshots, so unchanged groups do not need their metadata duplicated on every commit.
How the two-level pruning pipeline eliminates files before touching object storage
Planning starts with a catalog lookup for the current metadata file’s location. The engine reads that file, identifies the current snapshot, and locates its manifest list. Metadata reads can themselves touch object storage. The saving comes from avoiding unnecessary manifest reads and postponing all data-file reads until pruning is complete.
At the first pruning level, the engine compares each manifest’s partition summary with the query predicate. If their ranges cannot overlap, the manifest is discarded. No GET is issued for that manifest. The planner skips every data file behind it without reading the entries for those files.
The Iceberg specification illustrates this with a table partitioned by day(event_time) and one manifest per day. A query for November opens that month’s manifests while skipping the rest of the year’s. Why can it skip so much? Each manifest represents a narrow partition range. If every manifest instead spans many months, the summaries overlap and offer little basis for rejection.
For surviving manifests, the planner evaluates file entries using partition filters and metrics filters. Partition filters compare the partition tuple with the query, while metrics filters use column bounds and null or NaN counts. Residual evaluation finds the parts of the predicate that must still run when the data is read. A file whose bounds exclude the requested values is rejected before even its Parquet footer is opened.
The spec sets a goal of O(1) remote calls for scan planning rather than O(n) calls that grow with partition or file count. Aggregation makes that goal possible by placing summaries above detailed inventories. It does not make metadata volume irrelevant. The number and organization of surviving manifests still determine how much fetching and decoding the planner performs before assembling scan tasks.
Where planning degrades: manifest fragmentation, wide tables, and the Avro format mismatch
Frequent streaming commits can accumulate many small manifests, each describing few files. The planner must fetch each manifest that remains in a separate request. What could have been a small set of parallel reads becomes many sequential or lightly parallelized object-storage round trips. When those manifests also span broad partition ranges, weak outer pruning exposes more of them to the next stage.
Avro is row-oriented, so reading a manifest entry means reading the row’s statistics maps even when a predicate uses only two or three columns. Those maps make up much of each entry. On a wide table, the planner transfers statistics for every column and uses only a small share.
This is a mismatch between storage layout and access pattern. The query asks about selected columns, but the manifest packages statistics by file entry. More files add rows to process, while more columns enlarge those rows. Fragmentation then spreads that work across more requests. A selective query can thus read a lot of metadata even when it ends up scanning little data.
Decoding takes work that measurements of I/O may miss. The maps become many small objects in the planning coordinator’s heap, and garbage collection can produce unpredictable latency spikes. A table with many small files can take seconds to plan a simple query because of the work its file inventory requires, independently of its data size. Data-side profiling misses the delay because the scan has not begun.
Practical controls for keeping manifest structure healthy as tables grow
The operational response is to maintain manifests as ingestion changes them. Spark’s rewrite_manifests procedure sorts data-file entries by fields in the partition spec and regroups them. That clustering tends to make partition ranges narrower, so manifest-level pruning has more chances to rule out whole groups. The ranges can still overlap. Consolidating small manifests also reduces the number of GETs needed during planning.
Snapshot expiration addresses a separate accumulation problem. Each snapshot has its own manifest list, while snapshot history enlarges the table metadata file. Expiration deletes expired snapshots’ manifest lists and removes manifests and data files that no live snapshot references. Shared files remain while they are still needed. This reclaims storage and limits the history processed at the start of planning.
Expiration is not a substitute for data compaction. Expiration removes old references, whereas compaction rewrites data files to reduce their count. Manifest rewriting reorganizes the inventory of those files, leaving the files themselves unchanged. For streaming tables, the recommended approach is to schedule rewriting in line with ingest frequency, because frequent checkpoints keep creating the conditions that consolidation corrects.
What v4's shift to Parquet manifests and a root manifest changes structurally
Maintenance can improve organization, but it cannot give Avro column projection. The spec describes v4 as supporting columnar statistics representation, and a companion proposal places typed per-column statistics in Parquet manifests. The spec states that v4 has not been formally adopted, so they should not be treated as released features.
In v1–v3, statistics are in separate maps keyed by column ID, and bounds are encoded as binary values. The proposed content_stats struct instead contains a typed sub-struct for each tracked column. Within it, bounds, value counts, and null counts have typed fields. This nesting gives Parquet a column structure to project. A two-column predicate on a 300-column table could read statistics for only those two columns out of all 300.
Columnar manifests also create pruning opportunities within a manifest. When entries are sorted by partition value, row-group statistics can rule out groups of entries, and the Parquet page index can rule out pages within the groups that remain. Only the needed statistics columns then require decoding. The August 2026 development-list discussion raised whether Parquet should be the only v4 manifest format. The case for that choice included projection, avoiding dual-format maintenance, and avoiding an inconsistently implemented optional fast path.
The root manifest addresses a different structural cost. In v1–v3, each commit rewrites the flat manifest list in full, so index-writing work grows with manifest count. The proposed adaptive tree can inline small changes, leaving the rest of the index intact. Snapshot offloading would also move old snapshot history out of the metadata JSON.
How manifest structure affects workloads that query frequently and in parallel
A planning delay costs more when queries come in over and over or at the same time. Without engine-side or catalog-side caching, each query has to pay the cost of reading its manifests. For selective queries, that cost can exceed the data-read time. Even with a narrow predicate, broad partition summaries can force the planner to open many manifests before it can use file-level statistics.
Catalog-side scan planning provides a way to reuse that work. When the catalog handles planning, it can cache manifest content and completed planning results. A repeated identical plan can then be served without another round of object-storage reads. The engine replaces many manifest GETs with one HTTP round trip to the catalog. Repeated and templated queries are especially suited to this path.
Agents are a concrete instance of that pattern. A research or analytics agent may issue schema-discovery, sampling, aggregation, and validation queries within one tool-use loop, repeating templates as it refines its reasoning. Fragmented manifests make each iteration wait for planning. Manifest consolidation and catalog-side caching can shorten that path without changing the agent’s query logic.
Autonomous access also makes planning transparency important for accountability. A log of table access alone leaves out how the planner chose which files to read. The recommended audit trail includes which files were selected and which were skipped, because those decisions determine the data exposed to the query. Planning is therefore both a performance boundary and an operational record.
What well-structured Iceberg metadata looks like in practice, and how to get there
Healthy metadata gives each pruning layer a useful distinction to make. When manifests are clustered into narrow partition ranges that ideally do not overlap, the outer layer can rule out whole groups. Their count reflects the table’s data and query patterns. Bounded snapshot history keeps the entry point small. These properties depend on recurring maintenance.
Partition design determines how much that organization can accomplish. A predicate aligned with the partition transform can eliminate manifests before they are opened. A predicate on a non-partitioned column must instead rely on statistics inside them. For those queries, manifest consolidation and a useful data sort order become more important because the outer summary cannot do the same work. The maintenance choice follows from where pruning can occur.
Caching adds reuse to this well-organized planning path. Managed infrastructure that serves metadata through a cache can use both consolidation and catalog-side planning, so it can avoid fetching manifests afresh for every query. The gain is clearest for repeated plans. Novel queries still depend on the metadata that must be traversed, so caching and manifest maintenance address different sources of work.
If adopted, projected statistics would avoid reading unrelated columns, while the adaptive tree would reduce the metadata rewritten for small commits. Manifests would still need to be kept organized. For now, partition-aware rewriting, snapshot expiration, and planning-result reuse are the available controls, while the proposed architecture targets costs those controls cannot fully remove.