Service Level Objective Examples for Real-Time Analytics Infrastructure
Real-time analytics needs SLOs built around query latency and data freshness.
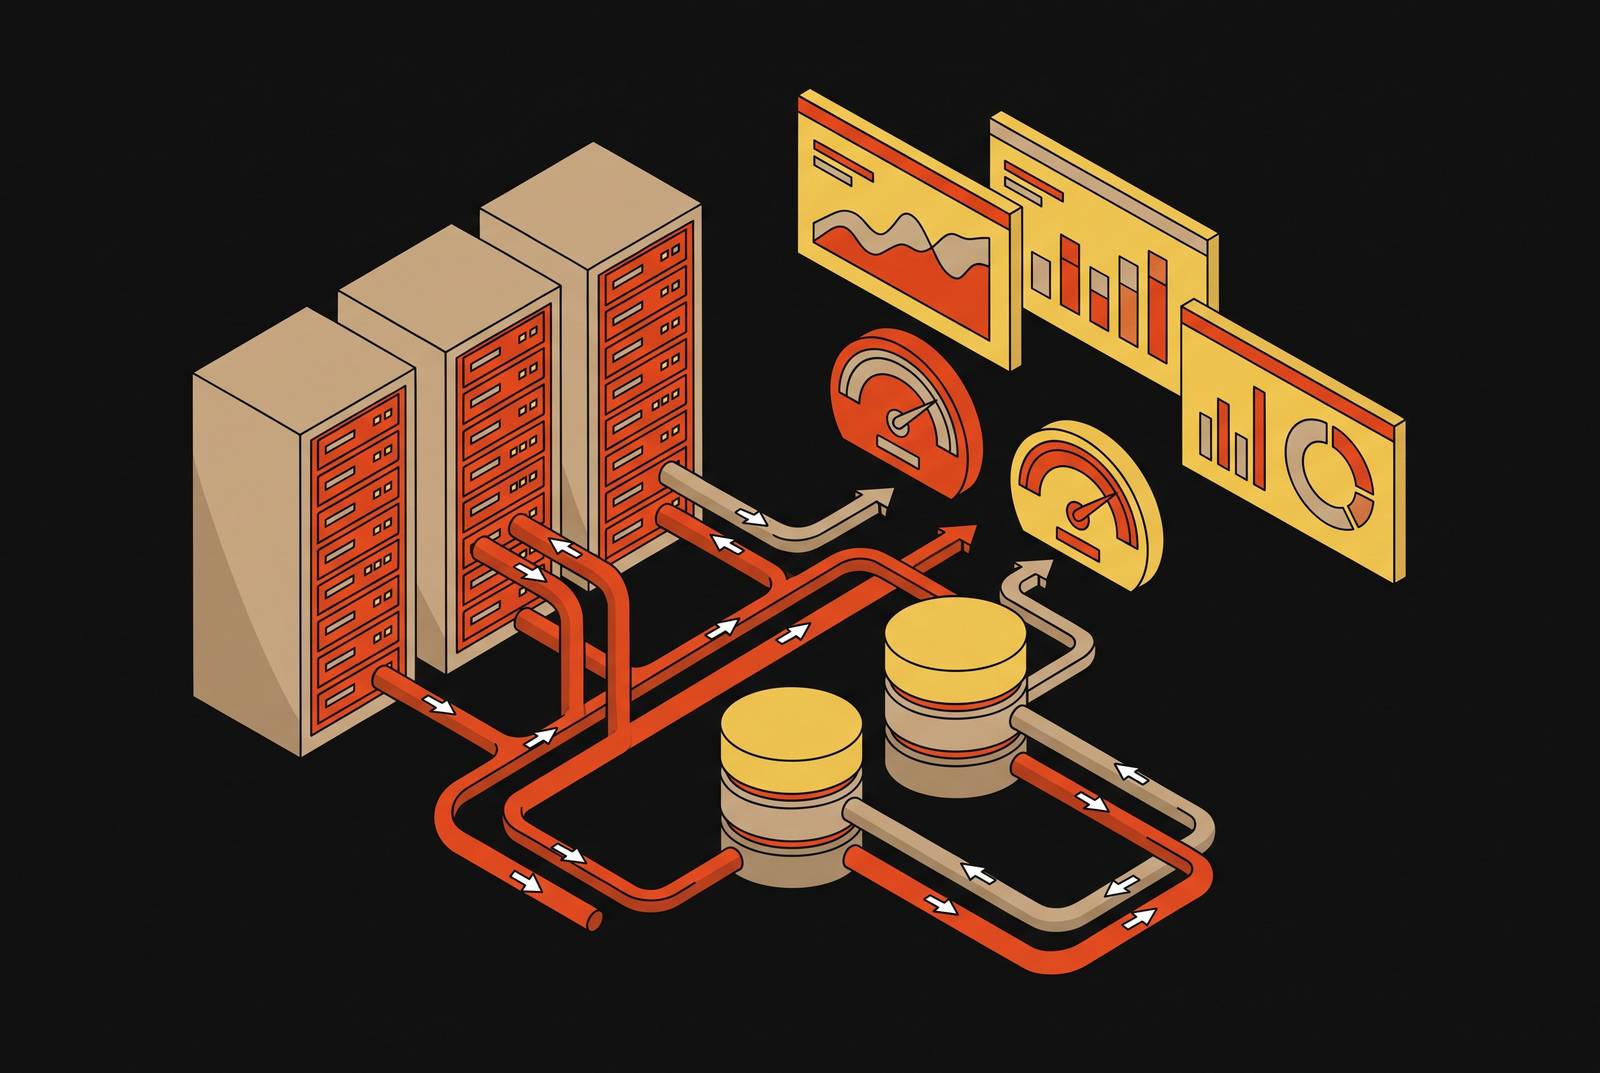
This article is about setting service level objectives for real-time analytics infrastructure, and the argument is simple: these systems need SLOs built around query latency percentiles, ingestion lag, availability, and error budgets, in place of the request/response conventions written for transactional databases. Teams that borrow transactional SLO templates end up measuring the wrong thing, and the fix is to build targets from how the system actually behaves under load.
Why Real-Time Analytics Systems Need Different SLOs
Real-time analytics infrastructure generates SLO requirements across at least four distinct dimensions: query latency percentiles, ingestion lag, availability, and error budgets. None of these map cleanly onto the request/response SLOs that transactional systems have used for years. Transactional SLOs measure whether individual writes and reads succeed and return quickly. An analytics SLO has to ask more of the system at once. It has to confirm that fresh data is actually there to query, that aggregations return inside a threshold users will tolerate, and that the system doesn't buckle under the kind of concurrency analytical workloads produce.
Why does this split matter so much in practice? Because the thing being counted is different. A transactional SLO counts requests, full stop. An analytics SLO has to separately track ingestion events, query executions, and in many cases pipeline lag, and each of those carries its own definition of what counts as an error. Treating them as one undifferentiated pool of "requests" makes the SLO stop reflecting what the system is actually doing. A query might succeed technically while running against data that's three minutes stale, and a transactional-style SLO has no way to catch that, while an analytics-style SLO can, because it must also capture whether fresh data is available to query, whether aggregations return within user-facing thresholds, and whether the system holds up under analytical concurrency.
That's the premise the rest of this piece works from. Because these four dimensions behave differently from each other and from transactional SLOs, each one needs its own worked example, calibrated to how the underlying system actually performs. That's what the next several sections build out, one dimension at a time.
How ClickHouse's architecture determines what SLO targets are achievable
Before setting a single number, it helps to understand what the architecture underneath will and won't tolerate. The targets a team can credibly commit to are bounded by how a columnar analytics database physically processes queries, including columnar storage, vectorized execution, sparse indexing, and asynchronous background merges, and by where the hot data sits relative to the query path. Skipping this step turns the SLO into a wish list instead of a commitment.
Take the merge process first. The MergeTree storage engine merges and transforms data asynchronously in the background, decoupling ingestion throughput from query performance, a key property when writing ingestion-lag SLOs.
Now consider where the data physically lives. When a query has to reach object storage, such as S3, for data that's been tiered out of NVMe cache, latency climbs in ways that are non-linear and hard to bound. That single fact has a direct consequence for how a latency SLO should be written: it must say explicitly whether it covers cached data, tiered data, or both. An architecture that keeps hot data in memory and never routes live queries through S3 can commit to tighter, more defensible p99 targets. Architectures that tier aggressively must either widen their latency SLOs for cold queries or exclude cold-data queries from the SLO scope.
Concurrency deserves particular attention here, because it's the blind spot SLO authors most often miss. This kind of system is built for a relatively small number of heavy analytical queries running in parallel, not thousands of lightweight concurrent requests. A p99 target tuned for a low-concurrency dashboard simply won't hold once concurrency rises, unless someone has done the capacity modeling to confirm it will. That means an SLO for a customer-facing analytics product needs a stated concurrency assumption built into it alongside the latency number.
Tier selection gates what's structurally possible, too. The managed service's entry-level tier cannot scale, manually or automatically, while its higher tier carries a significant monthly cost but opens the door to auto-scaling and multi-zone replication. A team that writes an always-on availability SLO while running on the Basic tier has created a mismatch baked into the architecture itself: that tier can't add capacity in response to load, so the SLO gets violated not by bad luck but by design.
Query latency SLOs: what p50, p95, and p99 targets look like in production
Query latency SLOs for real-time analytics should be written as percentile targets against a defined query class and a stated concurrency level, never as a single average. Why does the percentile choice matter as much as the number itself? Because average latency hides exactly the tail behavior users actually feel. A system can report a perfectly respectable average while a meaningful slice of users sit there waiting far longer than they should.
One large-scale observability deployment handles hundreds of billions of spans per day across three data centers and serves vast query volumes per minute across the fleet with low average latency. That average includes deep analytical queries that earlier systems couldn't serve at all, which tells you sub-100ms average latency is achievable at very high query volume. But the average is the number that gets reported publicly, not the number a reliability engineer should write an SLO against. The p99 for that same workload would run substantially higher, and the p99, not the average, is the figure that belongs in the SLO document.
Schema design moves these numbers just as much as raw infrastructure does. Langfuse's "simplify for scalability" rewrite collapsed its data model into a single immutable observations table with no joins and no deduplication, which delivered millisecond initial table loads and at least 10x faster dashboard load times for large projects. That's a direct, measurable demonstration of how a schema decision moves a latency SLO target, not an abstract design preference.
So what does a worked target structure actually look like? Set a p50 tight enough to represent what a typical user experiences; the median is the number the SLO author is committing to. Set a p95 at the point where the long tail starts, which is usually where schema and indexing choices start to show their effect. Set a p99 as the contractual ceiling, the number that triggers an error budget burn and eventually an incident if it holds for too long. Every one of these targets needs to name the query class it applies to, something like "single-tenant aggregation over a trailing month," along with the concurrency level assumed, such as "up to 20 concurrent users". Treat any numeric example as a template to calibrate against a specific workload, not a guarantee, because the achievable number depends entirely on the architectural conditions discussed above.
Schema decisions deserve a second look here, because they're the highest-leverage lever available. Primary key and sort order determine query performance directly: a query that hits the sort key skips irrelevant data blocks, while one that doesn't performs a full scan at the column level, a gap that can run an order of magnitude in latency. Skip indexes, such as bloom filters, let the engine skip entire data blocks when filtering on columns outside the primary key, which matters whenever dashboard filters touch dimensions the primary key doesn't cover. PREWHERE filters rows before reading every column, cutting I/O materially for queries that filter on a few fields while selecting many others. And resolving joins at ingestion time, rather than at query time, keeps the query path join-free, since a join that's cheap in a transactional database can get expensive fast at analytics scale.
Ingestion lag SLOs: defining freshness for real-time pipelines
Query latency answers how fast a question gets answered. Ingestion lag answers a different question entirely: how fresh is the data being queried. This dimension is often left undefined in SLO documents, even though it's the guarantee end users care about most when they ask whether a system is actually "real-time". An ingestion lag SLO sets the maximum acceptable delay between an event happening and that event becoming queryable. Without an explicit number here, "real-time" is a marketing phrase, not an engineering commitment.
The asynchronous merge process discussed earlier is the architectural fact that shapes this SLO directly. This write-optimized storage layer accepts inserts quickly, but merges and transforms the data asynchronously in the background, so rows are queryable before merges finish even though certain aggregations and deduplication behaviors depend on merge state completing. That means an ingestion lag SLO has to specify precisely what "queryable" means: raw rows visible immediately, or the fully merged and deduplicated state. Those are two different promises, and conflating them is where a lot of freshness SLOs go wrong.
Cresta's production setup offers a useful anchor for how this gets handled in practice. Cresta runs tens of millions of daily records across three dedicated clusters: one for real-time aggregation, one for raw event storage, and one for observability, feeding the company's Director UI for enterprise customers querying billions of records. Splitting clusters by workload type is itself an ingestion-lag decision, since it isolates the real-time aggregation path from heavier historical queries that would otherwise compete for the same resources.
What should the SLO document actually contain? It needs a measurement point, defined as the time from event generation, or a Kafka offset commit, to query visibility in the analytics database. It needs threshold examples calibrated to the product type. For an observability pipeline, such as distributed tracing, seconds-level lag is typically the upper bound. LinkedIn's deployment supports near-real-time troubleshooting, which points toward a lag SLO measured in seconds rather than minutes. For a customer-facing analytics dashboard, a lag SLO somewhere between tens of seconds and a few minutes is common for aggregated metrics, while sub-second ingestion-to-query is achievable for raw event visibility specifically. For a risk engine or fraud detection system, the lag SLO may need to be written in milliseconds, which forces architectural trade-offs like synchronous insert acknowledgment and no asynchronous buffering, trading throughput away for freshness.
The document should also state the pipeline path the SLO covers, from source through Kafka through ingest to query visibility, with the lag budget allocated across each hop rather than treated as one unexplained number. The Cresta and LinkedIn figures here work as calibration points, giving a sense of what's achievable at scale, not templates to copy wholesale.
Availability SLOs: what uptime targets mean in a replicated, multi-zone system
What "availability" means in a managed analytics database context depends heavily on replication topology and tier, so the target-setting process has to start somewhere other than picking a number of nines. An availability SLO has to name the replication topology and tier it assumes, because the same numeric target, say four nines, is entirely achievable under one configuration and structurally impossible under another.
Replication topology sets the floor. Multi-AZ replication with two or more replicas provides the architectural basis for high availability SLOs, while single-zone, single-replica configurations, such as a managed service's entry-level tier, cannot support the same targets because there is no failover path. Cross-Region Replication, announced at Open House 2026, brings an active-passive failover architecture with recovery time measured in minutes and recovery point measured in seconds, intended for enterprise resiliency. Teams planning disaster-recovery-grade availability SLOs should treat that capability as a future option to plan around rather than a guarantee available to every deployment today.
One might argue that a published uptime percentage from a cloud provider settles the question. It doesn't, and the gap matters. Published SLO targets, in other words, describe a ceiling achievable under ideal configuration, not a guarantee that holds regardless of how a team has actually deployed the system. The practical response is to test availability under the specific configuration a team is running, rather than inheriting whatever number the provider has published.
A workable availability SLO for a production analytics system defines availability as the fraction of time the system can successfully execute a query against a defined endpoint, measured over a rolling 30-day window. It should exclude planned maintenance windows, assuming proper notice was given, along with outages caused by upstream dependencies outside the system's own control. And it should specify the measurement method as synthetic query probes run at a fixed interval against a representative query, not just an infrastructure heartbeat check, because infrastructure can report healthy while query execution underneath it is actually degraded.
Error budgets: how to calculate and consume them for an analytics workload
Error budgets are what turn the three preceding dimensions, latency, freshness, and availability, into something a team actually operates against day to day, rather than numbers sitting in a document. An error budget converts an SLO target into a concrete allowance for failure, the measurable gap between perfect performance and the target that's been set, and how a team tracks and spends that allowance shows whether the SLO functions as a living operational tool.
The math itself is straightforward. For a high-availability SLO measured over the window, that budget works out to a small fraction of all the request-equivalents that occurred in that period. Budget remaining is just the budget total minus the bad events observed so far. As that remaining budget approaches zero, the operational response is to slow down: new deployments and risky changes pause until the window resets or reliability improvements buy back some of the budget.
What makes this genuinely useful, rather than a reporting exercise, is tracking it directly against the telemetry the system is already producing: ingestion events, query executions, and availability probes, each carrying its own error definition, feeding into a shared budget that latency, freshness, and uptime targets all draw from together. A team that tracks error budget this way can see, in real time, whether a risky schema migration or a new dashboard feature is actually safe to ship this week, or whether the budget from an earlier ingestion-lag violation has already been spent.